What does a pull request add that a local merge does not?
covers: lo-3
Answer
In git terms: nothing. The merge commit a pull request produces is the same
merge commit you could have made with git merge on your own machine. Everything
a pull request adds sits around the merge.
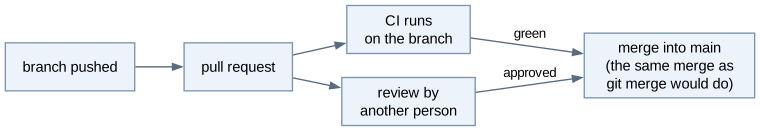
A review moment. Somebody who did not write the change reads it before it
reaches main. That is the only mechanism in the course that catches a mistake
before it becomes everybody’s problem.
A discussion attached to the change. The comments live with the diff, not in a chat that scrolls away, so the reasoning is still readable a year later next to the code it is about.
A CI run on the branch. The build and the tests run on the merged result
before the merge, so main stays green by construction rather than by luck.
And afterwards the history records who reviewed what — which is not bureaucracy but the answer to "how did this get in?" when something breaks.
Points the answer must contain:
-
Technically nothing in git terms — the merge is the same
-
It adds a review moment, a discussion attached to the change, and a CI run on the branch before the merge
-
The history then records who reviewed what
When do you need a fork, and when is a branch enough?
covers: lo-5
Answer
One question decides it: do you have write access to the repository?
| Situation | What you need |
|---|---|
Your team’s project repository, you are a collaborator |
a branch in that repository — you can push, nothing else is needed |
Somebody else’s repository: the exercise repositories of this course, an open-source project, another team’s repo |
a fork — your own copy under your account, because you cannot push to theirs |
A fork is a copy of the repository on GitHub under your own account, with a link back to the original. You have write access to the copy and none to the original.
That is also the answer to why pull requests exist in this shape: the pull request is the mechanism by which somebody who may not push can still propose a change — the owner keeps the decision, you keep the work. A branch in a shared repository is the same idea with the permission question already settled.
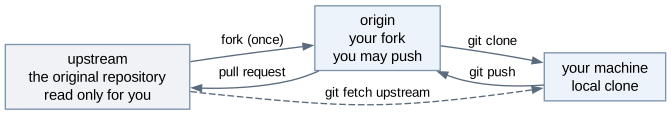
In this course: the exercise repositories are forked, the team project repository is not — there everybody is a collaborator and works on branches.
Points the answer must contain:
-
A branch is enough when you have write access; a fork is needed when you do not
-
A fork is your own copy on GitHub, with write access for you and none to the original
-
The pull request is what lets somebody without write access propose a change
Walk through opening a pull request from a fork
covers: lo-5, lo-1
Answer
gh repo fork htl-leonding-example/jg03-syp-git-basics --clone   # fork + clone
cd jg03-syp-git-basics

# after a fork made in the web interface instead:
git clone git@github.com:<you>/jg03-syp-git-basics.git
cd jg03-syp-git-basics
git remote add upstream git@github.com:htl-leonding-example/jg03-syp-git-basics.git

git remote -v          # origin = your fork, upstream = the original
git switch -c feature/exercise-3
# ... commits ...
git push -u origin feature/exercise-3
gh pr create --repo htl-leonding-example/jg03-syp-git-basics --fill
The part to understand rather than memorise is the two remotes. origin is
your fork — that is where git push goes, and it is the only repository you may
write to. upstream is the original — you only ever read from it, with git
fetch upstream. Setting upstream is a manual step after a fork made in the
browser; gh repo fork --clone does it for you.
The push therefore goes to your fork, and the pull request is opened from your branch there against the original. Nothing you do can change the original until somebody with write access merges it.
Keeping the fork in step, before starting the next branch:
git
fetch upstream
git switch main
git merge upstream/main # or, in one step: gh repo sync
git pushA fork does not update itself. Skipping this means every new branch starts from a
week-old main, and the pull request arrives carrying commits the original
already has.
The classic mistakes: working on main of your own fork (nothing stops you, and
then the pull request contains everything you ever did), forgetting the
upstream remote, and opening the pull request against your own fork’s main
instead of the original.
Points the answer must contain:
-
Fork on GitHub, clone your fork, add
upstreampointing at the original -
Branch, commit, push to
origin— your fork — then open the pull request against the original -
git fetch upstreamand merge before starting the next branch; a fork does not update itself
Which three questions does a pull request description answer?
covers: lo-1
Answer
-
What does this change, for the user of the system? Not "renamed the method" — "the attendance list can now be exported as CSV".
-
Why this way? One sentence on the alternative you rejected. This is the part the reviewer cannot reconstruct from the diff, and the part they would otherwise ask about.
-
How did you check it? The test, the command, the screenshot. It tells the reviewer what is already covered and, by omission, what is not.
## What
Attendance can be exported as CSV from the class view.

## Why this way
The school administration system imports CSV and nothing else. XLSX was
rejected because it pulls in a library for one feature.

## Checked
`ExportServiceTest` covers the empty list and the DST week; exported a real
class and imported it into the test instance.
Five lines of description save twenty minutes of somebody else’s time. A pull request that says "fixes stuff" forces the reviewer to reconstruct all three answers from the diff — which they will do badly, or not at all.
Points the answer must contain:
-
What changes, for the user of the system
-
Why this way — the rejected alternative in one sentence
-
How it was checked — test, command, evidence
What makes a review comment useful? Give an example of each kind
covers: lo-2
Answer
A useful comment is concrete, located and actionable: it names the case that goes wrong, points at the line, and says what would fix it. The author can act on it without a follow-up conversation.
| Useless | Useful |
|---|---|
"This is wrong." |
"If |
"I don’t like this name." |
"`data` here is a list of bookings; |
"LGTM" after ten seconds |
"Checked the CSV export against the sample file; the date column is off by a day in the DST week." |
Two habits carry most of the value. Review the change, not the person — write about what the code does, not about what the author failed to do; the same finding phrased as "line 42 divides by zero" and as "you forgot the empty case" gets a fix in one case and a defence in the other. And say what you checked, because that tells the author what was not checked. An approval is a statement about your reading, not about your trust in the author, so approve only what you actually understood.
Points the answer must contain:
-
Concrete, located, actionable: "empty list divides by zero at line 42, add a guard"
-
Useless: "this is wrong", "LGTM" after ten seconds
-
Review the change, not the person; say what you checked
Which rules apply to pull requests in this course?
covers: lo-4
Answer
Everything reaches main through a pull request, including documentation. One
path in means one place to look for how something got there, and documentation
errors are as public as code errors.
At least one review by another team member. Reviewing your own work does not work — you read what you meant to write.
CI green before merging. Not "merge now and fix it after": a red main blocks
everyone, and the fix always takes longer than the merge saved.
Small enough to read in one sitting. A pull request nobody can hold in their head gets approved rather than reviewed.
Two habits belong with the rules. Do not answer review comments by force-pushing
a rewritten branch — the reviewer then loses the thread of what changed since
their comment; push additional commits instead. And do not leave a pull request
open for a week: the branch drifts away from main and the merge turns into a
conflict exercise.
Points the answer must contain:
-
Everything goes through a pull request, including documentation
-
At least one review by another team member
-
CI green before merging, no "fix it after the merge"
-
Small enough to read in one sitting
Why is a two-thousand-line pull request a problem?
covers: lo-1, lo-4
Answer
Because it gets a signature instead of a review. Attention does not scale with diff size: past a few hundred lines the reviewer stops reading and starts scrolling, and "LGTM" on two thousand lines certifies nothing while looking exactly like a real approval in the history.
It is also where behaviour changes hide. A pull request that mixes a rename of three hundred lines with one changed condition presents the reviewer with three hundred and one changes that all look mechanical — and the one that matters is indistinguishable from the noise.
The consequences compound: a huge pull request takes days to review, during which
the branch drifts from main, so the merge brings conflicts on top of everything
else.
The remedy is to split by intent, not by size: the rename is one pull request, the behaviour change is another. Each is then reviewable in one sitting, and the history records two decisions instead of one lump.
Points the answer must contain:
-
It gets a signature instead of a review
-
Behaviour changes hide inside mechanical changes such as renames
-
Split it: one pull request per intent